Window Functions in SQL: ROW_NUMBER, RANK, LAG, Running Totals and Frames
By Skillancy Editorial Team · 20 October 2026 · 16 min read
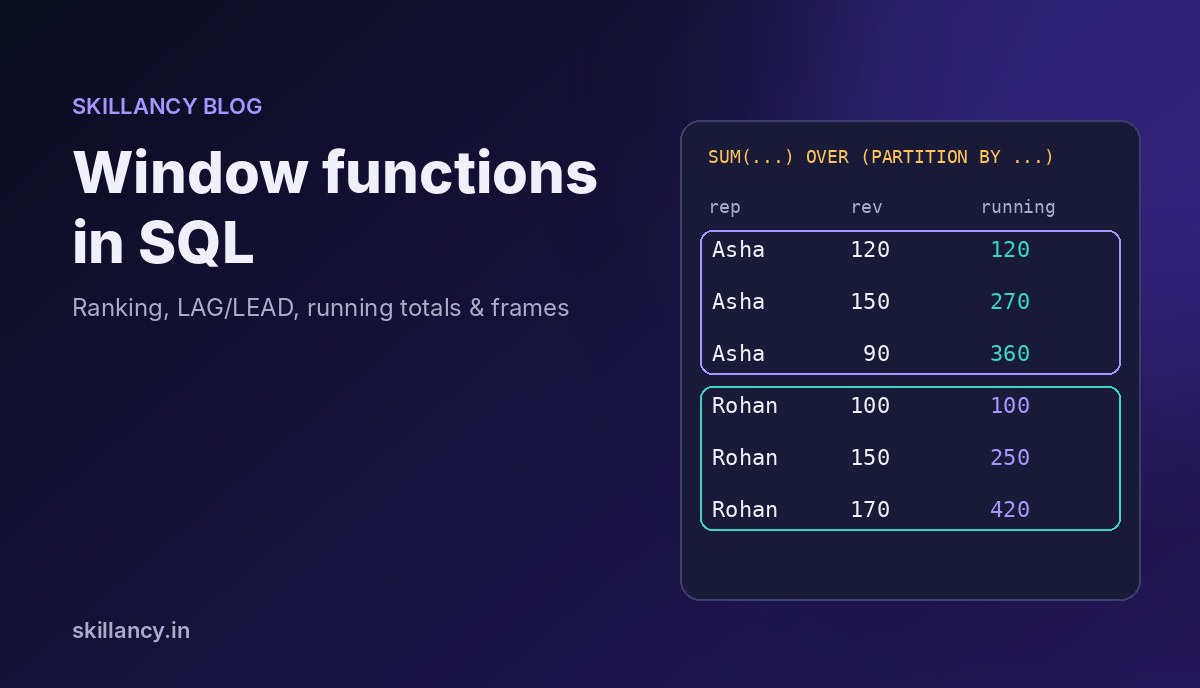
Window functions in SQL calculate a value for every row using a group of related rows, called a window, without collapsing those rows the way GROUP BY does. They are how analysts write running totals, rankings, month-over-month changes, moving averages and "top N per group" queries in a single, readable statement. They also show up in almost every mid-level SQL interview. This guide walks through every window function a data analyst needs, with one small dataset, the real output of every query, and the mistakes that trip people up.
The sample data
All examples use a sales table with three months of revenue (in ₹ thousands) for four sales reps in two regions:
| rep | region | month | revenue |
|---|---|---|---|
| Asha | North | 2026-01-01 | 120 |
| Asha | North | 2026-02-01 | 150 |
| Asha | North | 2026-03-01 | 90 |
| Kabir | South | 2026-01-01 | 80 |
| Kabir | South | 2026-02-01 | 95 |
| Kabir | South | 2026-03-01 | 110 |
| Meera | South | 2026-01-01 | 200 |
| Meera | South | 2026-02-01 | 180 |
| Meera | South | 2026-03-01 | 210 |
| Rohan | North | 2026-01-01 | 100 |
| Rohan | North | 2026-02-01 | 150 |
| Rohan | North | 2026-03-01 | 170 |
A few later examples also use a daily_orders table (one week of daily order counts) and a logins table (user logins by date). Every query on this page was run against PostgreSQL. You can paste the tables and queries into the free Skillancy SQL compiler and run them in your browser.
Window functions vs GROUP BY
GROUP BY collapses rows: one output row per group.
SELECT region, SUM(revenue) AS region_revenue
FROM sales
GROUP BY region
ORDER BY region;| region | region_revenue |
|---|---|
| North | 780 |
| South | 875 |
A window function keeps every row and attaches the group's value to each one. Here is February, with each rep's region total alongside their own revenue:
SELECT rep, region, month, revenue,
       SUM(revenue) OVER (PARTITION BY region) AS region_revenue
FROM sales
WHERE month = DATE '2026-02-01'
ORDER BY region, rep;| rep | region | month | revenue | region_revenue |
|---|---|---|---|---|
| Asha | North | 2026-02-01 | 150 | 300 |
| Rohan | North | 2026-02-01 | 150 | 300 |
| Kabir | South | 2026-02-01 | 95 | 275 |
| Meera | South | 2026-02-01 | 180 | 275 |
That is the core idea: you can compare a row to its group (its share, its rank, the previous row) without a self join or a subquery for every calculation.
The anatomy of OVER()
function_name(expression) OVER (
  PARTITION BY column      -- optional: split rows into independent groups
  ORDER BY column          -- optional: order rows inside each group
  ROWS BETWEEN ... AND ... -- optional: the frame, which rows count
)| Part | What it does | If you leave it out |
|---|---|---|
| PARTITION BY | Restarts the calculation for each group | The whole result set is one window |
| ORDER BY | Orders rows inside each window | Ranking and LAG/LEAD have no meaning; aggregates use the whole partition |
| Frame | Limits the rows used, e.g. the last 3 | With ORDER BY, defaults to "start of partition up to the current row and its ties" |
When window functions run
SQL evaluates a query in a fixed logical order, and window functions run late:
1. FROM and JOIN
2. WHERE
3. GROUP BY
4. HAVING
5. Window functions
6. SELECT expressions and DISTINCT
7. ORDER BY
8. LIMIT
Two consequences matter in practice. First, you cannot filter on a window function in WHERE, because WHERE runs before the window is computed:
SELECT rep, revenue, RANK() OVER (ORDER BY revenue DESC) AS rnk
FROM sales
WHERE RANK() OVER (ORDER BY revenue DESC) = 1;
PostgreSQL rejects this with the error window functions are not allowed in WHERE. Wrap the query in a CTE or subquery and filter outside it, as the top-N example below shows. Second, because window functions run after GROUP BY, you can apply them to aggregates, as in SUM(SUM(revenue)) OVER ().
Ranking functions: ROW_NUMBER, RANK and DENSE_RANK
The three ranking functions differ only in how they treat ties. February is useful because Asha and Rohan both made 150:
SELECT rep, revenue,
       ROW_NUMBER() OVER (ORDER BY revenue DESC, rep) AS row_num,
       RANK()       OVER (ORDER BY revenue DESC) AS rnk,
       DENSE_RANK() OVER (ORDER BY revenue DESC) AS dense_rnk
FROM sales
WHERE month = DATE '2026-02-01'
ORDER BY revenue DESC, rep;| rep | revenue | row_num | rnk | dense_rnk |
|---|---|---|---|---|
| Meera | 180 | 1 | 1 | 1 |
| Asha | 150 | 2 | 2 | 2 |
| Rohan | 150 | 3 | 2 | 2 |
| Kabir | 95 | 4 | 4 | 3 |
- ROW_NUMBER gives every row a unique number, even for ties. Add a tie-breaker column (here
rep) so the result is repeatable. - RANK gives ties the same number and then skips: 1, 2, 2, 4.
- DENSE_RANK gives ties the same number without gaps: 1, 2, 2, 3.
Which one to use depends on the question. "Exactly one row per group" needs ROW_NUMBER. "Everyone who shares first place" needs RANK or DENSE_RANK. "The third-highest distinct salary" needs DENSE_RANK.
Top N per group
This is the most common window-function interview question. Find each region's single best month, by any rep:
WITH ranked AS (
  SELECT rep, region, month, revenue,
         ROW_NUMBER() OVER (PARTITION BY region ORDER BY revenue DESC, rep) AS rn
  FROM sales
)
SELECT region, rep, month, revenue
FROM ranked
WHERE rn = 1
ORDER BY region;| region | rep | month | revenue |
|---|---|---|---|
| North | Rohan | 2026-03-01 | 170 |
| South | Meera | 2026-03-01 | 210 |
Change rn = 1 to rn <= 3 for the top three. If you are new to the WITH syntax, our guide to CTE in SQL explains it step by step.
Keeping only the latest row per entity
The same pattern removes duplicates or picks each customer's most recent record, by ordering descending and keeping row 1:
WITH ranked AS (
  SELECT rep, month, revenue,
         ROW_NUMBER() OVER (PARTITION BY rep ORDER BY month DESC) AS rn
  FROM sales
)
SELECT rep, month AS latest_month, revenue AS latest_revenue
FROM ranked
WHERE rn = 1
ORDER BY rep;| rep | latest_month | latest_revenue |
|---|---|---|
| Asha | 2026-03-01 | 90 |
| Kabir | 2026-03-01 | 110 |
| Meera | 2026-03-01 | 210 |
| Rohan | 2026-03-01 | 170 |
LAG and LEAD: comparing with the previous or next row
LAG reads a value from an earlier row in the window; LEAD reads from a later one. They replace the self joins people used to write for month-over-month comparisons.
SELECT rep, month, revenue,
       LAG(revenue)  OVER (PARTITION BY rep ORDER BY month) AS prev_month,
       LEAD(revenue) OVER (PARTITION BY rep ORDER BY month) AS next_month,
       revenue - LAG(revenue) OVER (PARTITION BY rep ORDER BY month) AS change
FROM sales
WHERE rep IN ('Asha', 'Meera')
ORDER BY rep, month;| rep | month | revenue | prev_month | next_month | change |
|---|---|---|---|---|---|
| Asha | 2026-01-01 | 120 | NULL | 150 | NULL |
| Asha | 2026-02-01 | 150 | 120 | 90 | 30 |
| Asha | 2026-03-01 | 90 | 150 | NULL | -60 |
| Meera | 2026-01-01 | 200 | NULL | 180 | NULL |
| Meera | 2026-02-01 | 180 | 200 | 210 | -20 |
| Meera | 2026-03-01 | 210 | 180 | NULL | 30 |
The first row of each partition has no previous row, so LAG returns NULL. You can supply a default, as in LAG(revenue, 1, 0), and the second argument lets you look further back, for example LAG(revenue, 12) for the same month last year in monthly data.
Month-over-month growth
SELECT rep, month, revenue,
       ROUND(100.0 * (revenue - LAG(revenue) OVER (PARTITION BY rep ORDER BY month))
             / LAG(revenue) OVER (PARTITION BY rep ORDER BY month), 1) AS mom_pct
FROM sales
WHERE rep = 'Kabir'
ORDER BY month;| rep | month | revenue | mom_pct |
|---|---|---|---|
| Kabir | 2026-01-01 | 80 | NULL |
| Kabir | 2026-02-01 | 95 | 18.8 |
| Kabir | 2026-03-01 | 110 | 15.8 |
Multiply by 100.0, not 100, so PostgreSQL does decimal rather than integer division. In real data, also guard against a previous value of 0 with NULLIF(LAG(...), 0).
Running totals
An aggregate with ORDER BY inside OVER becomes cumulative:
SELECT day, orders,
       SUM(orders) OVER (ORDER BY day) AS running_total
FROM daily_orders
ORDER BY day;| day | orders | running_total |
|---|---|---|
| 2026-03-01 | 40 | 40 |
| 2026-03-02 | 55 | 95 |
| 2026-03-03 | 35 | 130 |
| 2026-03-04 | 60 | 190 |
| 2026-03-05 | 70 | 260 |
| 2026-03-06 | 45 | 305 |
| 2026-03-07 | 80 | 385 |
Add PARTITION BY to restart the total for each store, customer or month.
Moving averages and window frames
A frame limits which rows the function sees. ROWS BETWEEN 2 PRECEDING AND CURRENT ROW means "this row and the two before it", which gives a 3-day moving average:
SELECT day, orders,
       ROUND(AVG(orders) OVER (
         ORDER BY day
         ROWS BETWEEN 2 PRECEDING AND CURRENT ROW
       ), 1) AS moving_avg_3d
FROM daily_orders
ORDER BY day;| day | orders | moving_avg_3d |
|---|---|---|
| 2026-03-01 | 40 | 40.0 |
| 2026-03-02 | 55 | 47.5 |
| 2026-03-03 | 35 | 43.3 |
| 2026-03-04 | 60 | 50.0 |
| 2026-03-05 | 70 | 55.0 |
| 2026-03-06 | 45 | 58.3 |
| 2026-03-07 | 80 | 65.0 |
The first two days average fewer than three values because there are not yet three rows. Mention that in a report, or start the chart from day three.
Common frame shapes:
| Frame | Rows included |
|---|---|
ROWS BETWEEN UNBOUNDED PRECEDING AND CURRENT ROW | Start of the window to this row (running total) |
ROWS BETWEEN 6 PRECEDING AND CURRENT ROW | This row and the 6 before it (7-row moving window) |
ROWS BETWEEN 1 PRECEDING AND 1 FOLLOWING | Previous, current and next row (centered window) |
ROWS BETWEEN UNBOUNDED PRECEDING AND UNBOUNDED FOLLOWING | The whole window |
ROWS vs RANGE
ROWS counts physical rows. RANGE groups rows whose ORDER BY values are equal (peers) and includes them together. With ties, the results differ:
SELECT rep, revenue,
       SUM(revenue) OVER (ORDER BY revenue, rep ROWS BETWEEN UNBOUNDED PRECEDING AND CURRENT ROW) AS rows_total,
       SUM(revenue) OVER (ORDER BY revenue RANGE BETWEEN UNBOUNDED PRECEDING AND CURRENT ROW)    AS range_total
FROM sales
WHERE month = DATE '2026-02-01'
ORDER BY revenue, rep;| rep | revenue | rows_total | range_total |
|---|---|---|---|
| Kabir | 95 | 95 | 95 |
| Asha | 150 | 245 | 395 |
| Rohan | 150 | 395 | 395 |
| Meera | 180 | 575 | 575 |
Asha and Rohan tie at 150, so RANGE adds both of them into Asha's row as well. The default frame when you write ORDER BY without a frame is RANGE, which is why a running total over a column with duplicate values can "jump" on tied rows. When you mean "row by row", write ROWS explicitly.
Percent of total and share of group
Window aggregates make share calculations one line each. Because window functions run after GROUP BY, you can wrap an aggregate: SUM(SUM(revenue)) OVER () is the grand total of the grouped sums.
SELECT rep, region, SUM(revenue) AS q1_revenue,
       ROUND(100.0 * SUM(revenue) / SUM(SUM(revenue)) OVER (), 1) AS pct_of_company,
       ROUND(100.0 * SUM(revenue) / SUM(SUM(revenue)) OVER (PARTITION BY region), 1) AS pct_of_region
FROM sales
GROUP BY rep, region
ORDER BY region, q1_revenue DESC;| rep | region | q1_revenue | pct_of_company | pct_of_region |
|---|---|---|---|---|
| Rohan | North | 420 | 25.4 | 53.8 |
| Asha | North | 360 | 21.8 | 46.2 |
| Meera | South | 590 | 35.6 | 67.4 |
| Kabir | South | 285 | 17.2 | 32.6 |
An empty OVER () means "the whole result set".
NTILE: splitting into buckets
NTILE(n) divides ordered rows into n roughly equal buckets, which is useful for quartiles, deciles and "top half vs bottom half" analysis:
SELECT rep, SUM(revenue) AS q1_revenue,
       NTILE(2) OVER (ORDER BY SUM(revenue) DESC) AS half
FROM sales
GROUP BY rep
ORDER BY q1_revenue DESC;| rep | q1_revenue | half |
|---|---|---|
| Meera | 590 | 1 |
| Rohan | 420 | 1 |
| Asha | 360 | 2 |
| Kabir | 285 | 2 |
FIRST_VALUE and the LAST_VALUE trap
FIRST_VALUE returns the first value in the frame. LAST_VALUE looks like its mirror, but with the default frame it returns the current row, because the default frame ends at the current row:
SELECT rep, month, revenue,
       FIRST_VALUE(revenue) OVER (PARTITION BY rep ORDER BY month) AS first_rev,
       LAST_VALUE(revenue)  OVER (PARTITION BY rep ORDER BY month) AS last_rev_wrong
FROM sales
WHERE rep = 'Asha'
ORDER BY month;| rep | month | revenue | first_rev | last_rev_wrong |
|---|---|---|---|---|
| Asha | 2026-01-01 | 120 | 120 | 120 |
| Asha | 2026-02-01 | 150 | 120 | 150 |
| Asha | 2026-03-01 | 90 | 120 | 90 |
Extend the frame to the end of the partition to get the true last value:
SELECT rep, month, revenue,
       LAST_VALUE(revenue) OVER (
         PARTITION BY rep ORDER BY month
         ROWS BETWEEN UNBOUNDED PRECEDING AND UNBOUNDED FOLLOWING
       ) AS last_rev
FROM sales
WHERE rep = 'Asha'
ORDER BY month;| rep | month | revenue | last_rev |
|---|---|---|---|
| Asha | 2026-01-01 | 120 | 90 |
| Asha | 2026-02-01 | 150 | 90 |
| Asha | 2026-03-01 | 90 | 90 |
Reusing a window with the WINDOW clause
When several functions share the same window, name it once:
SELECT rep, month, revenue,
       ROUND(AVG(revenue) OVER w, 1) AS avg_so_far,
       MAX(revenue) OVER w AS best_so_far
FROM sales
WHERE rep = 'Rohan'
WINDOW w AS (PARTITION BY rep ORDER BY month)
ORDER BY month;| rep | month | revenue | avg_so_far | best_so_far |
|---|---|---|---|---|
| Rohan | 2026-01-01 | 100 | 100.0 | 100 |
| Rohan | 2026-02-01 | 150 | 125.0 | 150 |
| Rohan | 2026-03-01 | 170 | 140.0 | 170 |
Advanced pattern: gaps and islands (login streaks)
"Find each user's consecutive-day streaks" is a classic hard interview question. The trick: for consecutive dates, the date minus its row number stays constant, so that difference identifies each streak.
The logins table has user 1 logging in on 1, 2, 3, 5 and 6 March, and user 2 on 2, 4, 5, 6 and 7 March.
WITH numbered AS (
  SELECT user_id, login_date,
         login_date - (ROW_NUMBER() OVER (PARTITION BY user_id ORDER BY login_date))::int AS grp
  FROM logins
)
SELECT user_id,
       MIN(login_date) AS streak_start,
       MAX(login_date) AS streak_end,
       COUNT(*) AS days
FROM numbered
GROUP BY user_id, grp
ORDER BY user_id, streak_start;| user_id | streak_start | streak_end | days |
|---|---|---|---|
| 1 | 2026-03-01 | 2026-03-03 | 3 |
| 1 | 2026-03-05 | 2026-03-06 | 2 |
| 2 | 2026-03-02 | 2026-03-02 | 1 |
| 2 | 2026-03-04 | 2026-03-07 | 4 |
Add one more step to get each user's longest streak:
WITH numbered AS (
  SELECT user_id, login_date,
         login_date - (ROW_NUMBER() OVER (PARTITION BY user_id ORDER BY login_date))::int AS grp
  FROM logins
),
streaks AS (
  SELECT user_id, grp, COUNT(*) AS days
  FROM numbered
  GROUP BY user_id, grp
)
SELECT user_id, MAX(days) AS longest_streak
FROM streaks
GROUP BY user_id
ORDER BY user_id;| user_id | longest_streak |
|---|---|
| 1 | 3 |
| 2 | 4 |
This assumes one row per user per day. If a user can log in several times a day, first take DISTINCT user_id, login_date.
Common mistakes with window functions in SQL
- Filtering in WHERE. Window results do not exist yet at that stage. Filter in an outer query. (Snowflake, BigQuery and Databricks also offer a
QUALIFYclause for this; PostgreSQL and MySQL do not.)
- Forgetting a tie-breaker in ROW_NUMBER. Without one, rows with equal values can come back in a different order on each run.
- Relying on the default frame. With ORDER BY, the default is RANGE up to the current row, which affects running totals over tied values and makes LAST_VALUE return the current row.
- Integer division in percentages. Use
100.0or cast to numeric.
- Expecting the window ORDER BY to sort the output. It only orders rows inside the calculation. Add a final ORDER BY for the result.
Window function interview questions to practice
1. Rank employees by salary within each department, keeping ties. (DENSE_RANK with PARTITION BY.)
2. Return the top 3 products by revenue in each category. (ROW_NUMBER in a CTE, filter <= 3.)
3. Calculate each customer's running spend by order date. (SUM OVER with PARTITION BY and ORDER BY.)
4. Show month-over-month revenue change and growth %. (LAG.)
5. Compute a 7-day moving average of daily active users. (AVG with ROWS BETWEEN 6 PRECEDING AND CURRENT ROW.)
6. Find each customer's first and most recent order. (FIRST_VALUE with a full frame, or ROW_NUMBER both ways.)
7. Find each user's longest login streak. (Gaps and islands.)
Our free set of SQL interview questions includes window-function problems with instant answer checking, and our guide to data analyst interview questions covers the other rounds.
Where window functions fit in your SQL learning path
Learn them after you are comfortable with filtering, aggregation and joins in SQL, and alongside CTEs, because most real window-function queries are written as a CTE plus a filter. After that, practice them on business questions: retention, funnels, rankings and trends. If you want structured practice with mentor feedback, the Data Analytics with Agentic AI program covers SQL from fundamentals to window functions on real case studies.
Frequently asked questions
What are window functions in SQL?
They are functions that compute a value for each row from a set of related rows, defined with an OVER clause, without collapsing rows the way GROUP BY does.
What is the difference between RANK and DENSE_RANK?
Both give tied rows the same rank. RANK then skips numbers (1, 2, 2, 4) while DENSE_RANK does not (1, 2, 2, 3).
What is the difference between PARTITION BY and GROUP BY?
GROUP BY returns one row per group. PARTITION BY, inside OVER, defines groups for the calculation but keeps every original row in the result.
Can I use a window function in a WHERE clause?
No. Window functions are computed after WHERE. Put the query in a CTE or subquery and filter on the result in the outer query.
Are window functions supported in MySQL?
Yes, MySQL supports window functions from version 8.0. PostgreSQL, SQL Server, Oracle, Snowflake and BigQuery all support them too, with small differences in extra features.
Do window functions slow queries down?
They usually need a sort by the PARTITION BY and ORDER BY columns, which can be expensive on large tables. Filtering early, selecting only needed columns and, where appropriate, indexing those columns help. On most analytical queries they are faster and clearer than the self joins they replace.
Recommended internal links
- Free online SQL compiler: https://skillancy.in/tools/sql-compiler
- 25 SQL interview questions with a live editor: https://skillancy.in/practice/sql-questions
- CTE in SQL guide: https://skillancy.in/blog/cte-in-sql
- Joins in SQL guide: https://skillancy.in/blog/joins-in-sql
- Data Analytics with Agentic AI program: https://skillancy.in/courses/data-analytics-with-agentic-ai
Sources and publishing references
PostgreSQL documentation: Window functions tutorial: https://www.postgresql.org/docs/current/tutorial-window.html
PostgreSQL documentation: Window function calls: https://www.postgresql.org/docs/current/sql-expressions.html#SYNTAX-WINDOW-FUNCTIONS
PostgreSQL documentation: Window functions reference: https://www.postgresql.org/docs/current/functions-window.html
All query outputs on this page were produced by running the queries against PostgreSQL.