RAG vs Fine-Tuning: What Should You Use for Generative AI Applications?
By Skillancy Editorial Team · 18 September 2026 · 4 min read
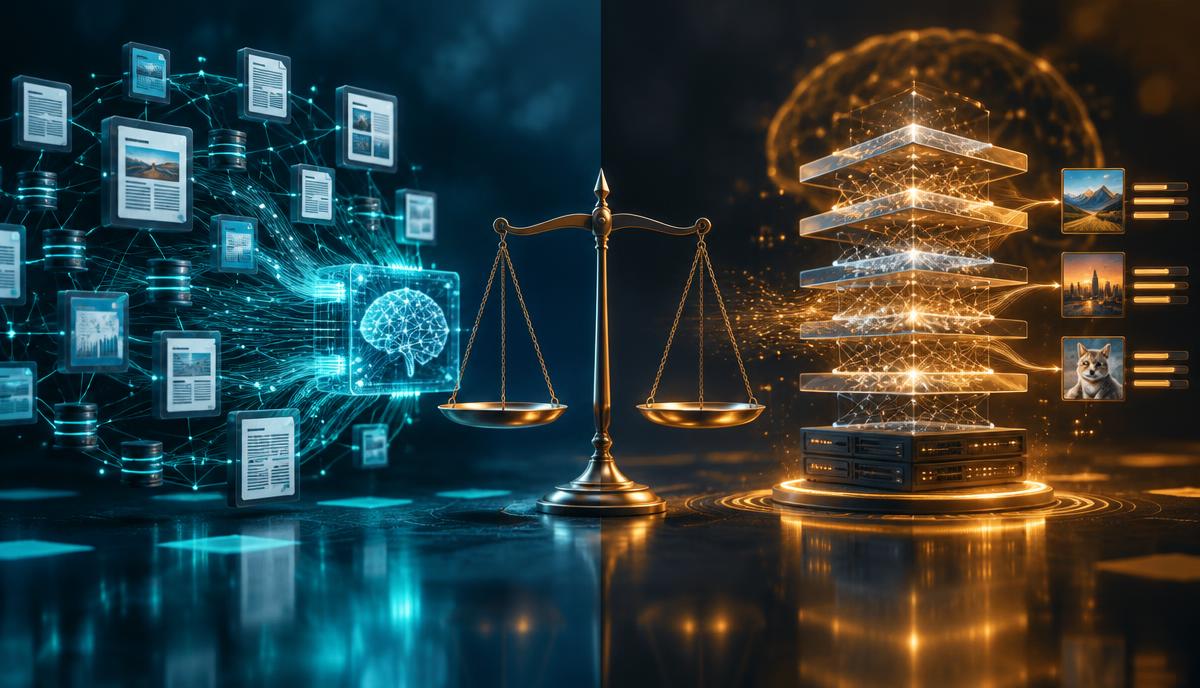
RAG and fine-tuning solve different problems. Retrieval-Augmented Generation adds relevant external information to a model at inference time. Fine-tuning changes model behavior by training it further on task-specific examples. Many teams should try prompting and RAG first, then consider fine-tuning when the use case has a clear behavioral or formatting requirement that those approaches cannot satisfy efficiently.
What is RAG?
A typical RAG system retrieves content from a knowledge source and supplies the relevant pieces to the LLM as context. The source might contain company policies, product documentation, reports or other approved information. The application then generates a response grounded in the retrieved context.
What is fine-tuning?
Fine-tuning continues model training on task-specific examples so the model learns patterns of behavior. It can be useful when you need a consistent style, classification behavior or task format across many inputs. Exact capabilities, economics and supported methods differ by model provider.
RAG vs fine-tuning: side-by-side
| Dimension | RAG | Fine-tuning |
|---|---|---|
| Main purpose | Supply relevant external context | Change learned behavior |
| Changing knowledge | Update the retrieval source | Usually requires another training cycle |
| Private company information | Common use case | Can be involved, but is not the main advantage |
| Style/format behavior | Can guide through prompts and examples | Can improve consistency for repeated patterns |
| Citations/traceability | Naturally supports source retrieval and citations | Does not itself provide current source evidence |
| Iteration | Change sources/prompts/retrieval settings | Prepare data and retrain |
| Typical first experiment | Prototype retrieval quality | Establish baseline and collect quality examples |
When RAG is usually the better starting point
- The information changes frequently.
- The knowledge is stored in documents or structured data outside the model.
- Users need answers grounded in specific sources.
- You want to inspect or update the source without retraining the model.
- The main challenge is context availability rather than model behavior.
When fine-tuning may be appropriate
- A stable task pattern needs consistent output behavior across many examples.
- The application needs a specific style, classification or transformation behavior.
- Prompting with representative examples is not sufficient for the target quality.
- The team has enough high-quality training examples and an evaluation process.
A practical decision tree
19. Ask: is the missing capability mainly knowledge or behavior?
20. If knowledge: test retrieval, source quality and context construction.
21. If behavior: improve the prompt and examples first, then evaluate whether fine-tuning is justified.
22. Keep a measurable evaluation set so every change can be compared with the baseline.
Common misconception: RAG is always cheaper
RAG adds infrastructure and retrieval complexity, while fine-tuning adds data preparation and training complexity. Neither is automatically cheaper in every scenario. Compare total system cost, maintenance burden, latency, update frequency and quality requirements.
Common misconception: fine-tuning adds current knowledge
Training on historical examples does not automatically make a model a live knowledge base. If users need current documents, a retrieval mechanism is usually more direct.
A strong evaluation plan
- Create representative questions and expected evidence or outputs.
- Measure retrieval quality separately from generation quality for RAG.
- Measure task success and consistency for fine-tuning candidates.
- Include hard cases, ambiguous requests and failure scenarios.
- Track changes over time instead of relying on anecdotal examples.
The bottom line
RAG and fine-tuning are complementary techniques, not competing labels. Start with the simplest architecture that solves the problem. For changing knowledge, retrieval is usually central. For stable behavior, fine-tuning may be useful after prompting and evaluation have established a clear need.
Frequently asked questions
Can RAG and fine-tuning be used together?
Yes. A system can use a tuned model for behavior and retrieval for current external knowledge when both are justified.
Does fine-tuning teach private company documents?
It can encode patterns from training data, but it is not a substitute for a live, traceable knowledge source when information changes.
Is RAG only for chatbots?
No. It can support search, extraction, analytics, support workflows and many other applications.
Should beginners start with fine-tuning?
Usually build a baseline with prompting and retrieval first so you understand the problem and have an evaluation benchmark.
What is the biggest RAG failure mode?
Poor retrieval can supply the model with irrelevant or incomplete context, leading to weak answers even when the model itself is capable.
Recommended internal links
- Generative AI program: https://skillancy.in/courses/generative-ai-program
- Generative AI roadmap: https://skillancy.in/generative-ai-roadmap-2026/
- Prompt engineering guide: https://skillancy.in/prompt-engineering-llms-2026/
Sources and publishing references
Skillancy current homepage: https://skillancy.in/
Google AI optimization guide: https://developers.google.com/search/docs/fundamentals/ai-optimization-guide
OpenAI publisher guidance: https://help.openai.com/en/articles/12627856-publishers-and-developers-faq